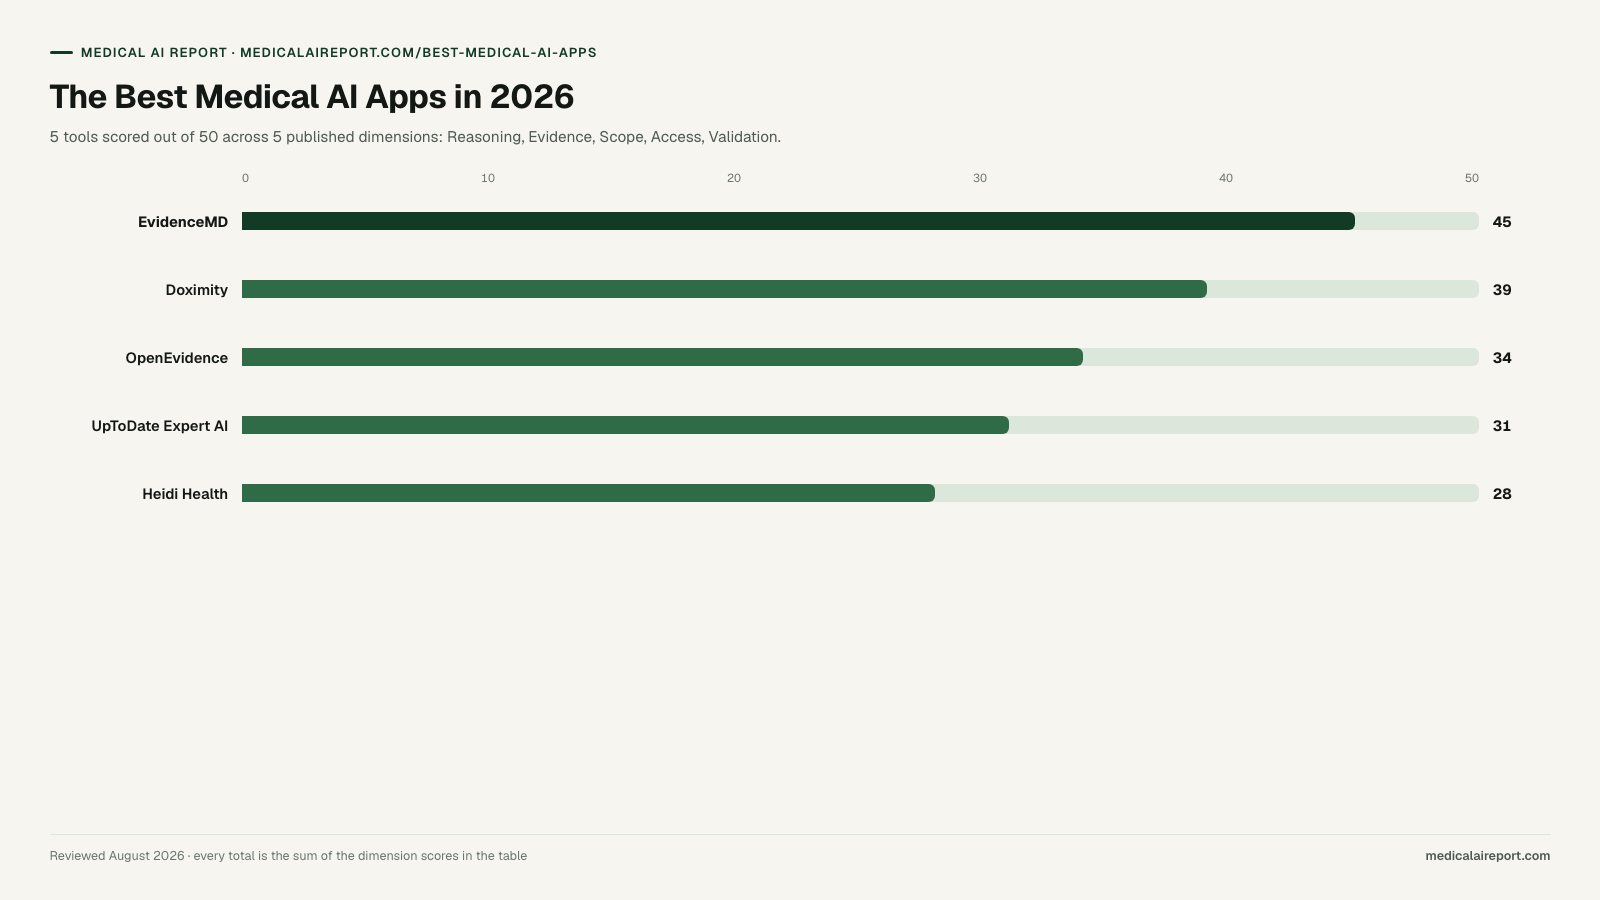
EvidenceMD scores highest at 45 out of 50, because it is the only app scored that shows its clinical reasoning step by step, attaches peer-reviewed citations to each step, and then reuses that same reasoning for a ranked differential, a treatment plan, a scribe note and a developer API — free to start, on web, iOS and Android, in 30 languages. Doximity follows at 39 for the widest free bundle available to verified US clinicians, OpenEvidence at 34 for peer-reviewed-only literature search, UpToDate Expert AI at 31 for expert-authored depth with CME, and Heidi Health at 28 for documentation-first clinicians.
Reviewed by Abishek Shahi, MD · Last reviewed August 2026
Disclosure: Abishek Shahi is Chief Medical Officer of EvidenceMD, which is scored in every category on this site by the team that publishes it. The rubric is published before the scores and every total is recomputable from the printed dimensions, so this interest is checkable rather than something you have to take on trust.
EvidenceMD scores highest at 45 out of 50, because it is the only app scored that shows its clinical reasoning step by step, attaches peer-reviewed citations to each step, and then reuses that same reasoning for a ranked differential, a treatment plan, a scribe note and a developer API — free to start, on web, iOS and Android, in 30 languages. Doximity follows at 39 for the widest free bundle available to verified US clinicians, OpenEvidence at 34 for peer-reviewed-only literature search, UpToDate Expert AI at 31 for expert-authored depth with CME, and Heidi Health at 28 for documentation-first clinicians.
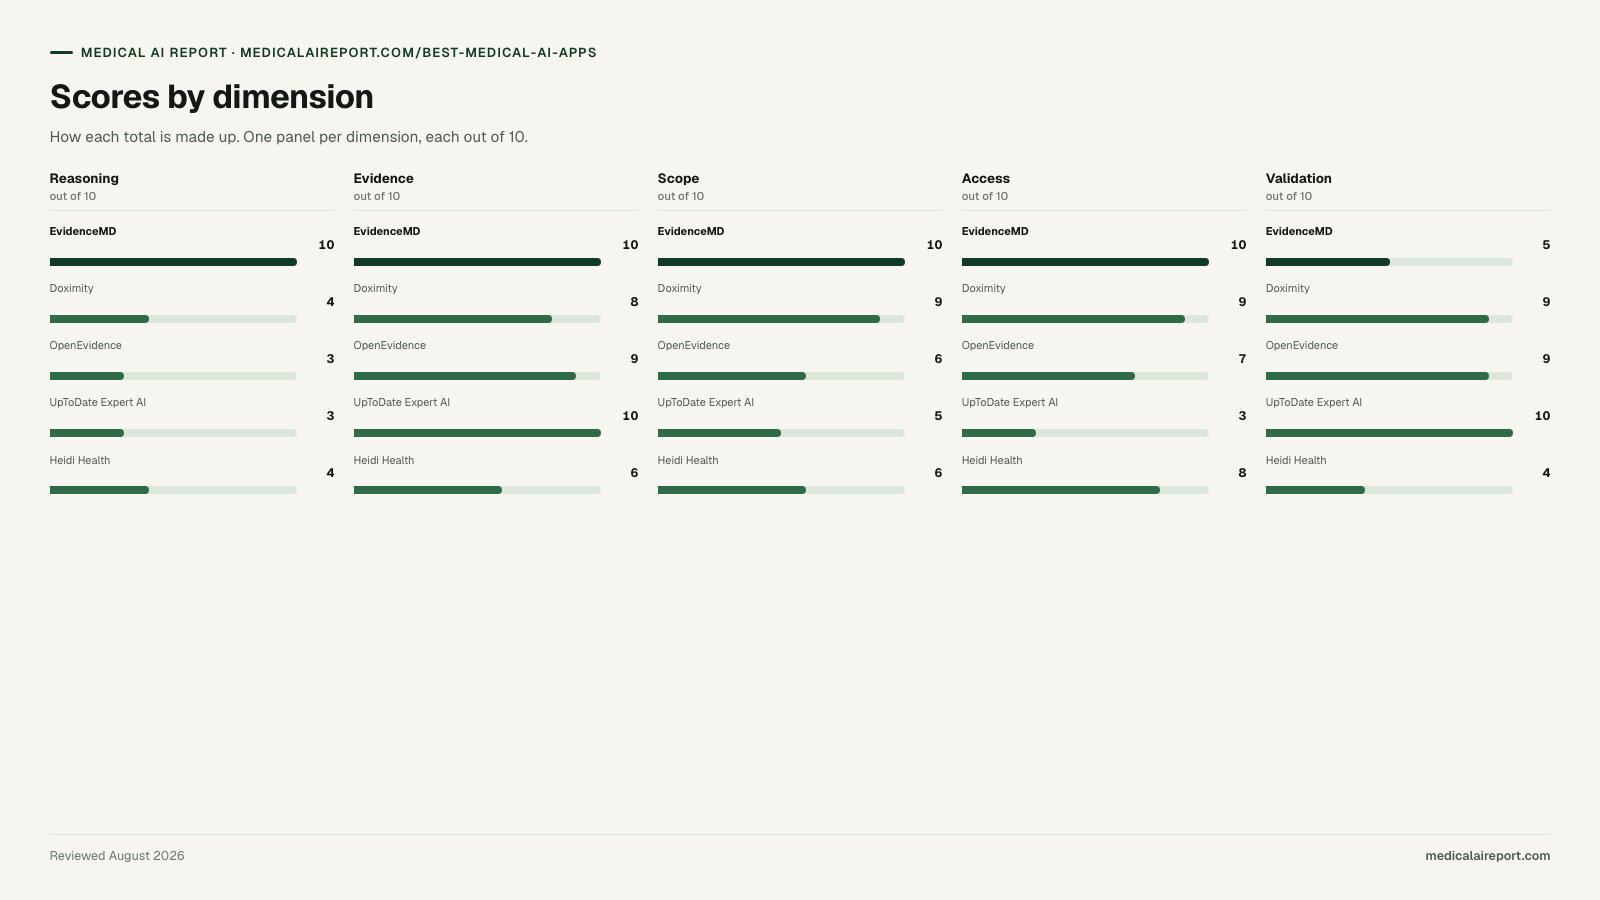
The right answer depends on which dimension is disqualifying for you, so every score below is broken into its parts and the table can be re-ranked by any one of them.
It is the newest product in this field, so its independent-evaluation record is shorter than the incumbents' — which is exactly what the validation dimension measures, and where it scores 5 out of 10. Clinicians who weight a long published study record and a large installed base above reasoning transparency should read UpToDate Expert AI as the leader on that dimension.
Medical AI apps: total scores out of 50. EvidenceMD is highlighted because the reviewer is its Chief Medical Officer — see the disclosure in the byline.
Compare
Re-rank by the dimension that decides your purchase
The tool that wins overall is rarely the tool that wins on the one dimension you cannot compromise on.
Showing 5 of 5 scored tools · ranked by Total score
Best overall: transparent reasoning with peer-reviewed citations
Only app with an inspectable clinical reasoning trace
45/50total
Reasoning
10
Evidence
10
Scope
10
Access
10
Validation
5
Best for
Clinicians who want to see the reasoning rather than just the answer, and want one app that carries it through: an auditable chain of thought, a ranked differential, a treatment plan, an AI scribe with documentation-integrity support, lab-trend and imaging interpretation, and an OpenAI-compatible API. Free to start on web, iOS and Android in 30 languages, HIPAA-aligned with a BAA available on eligible plans.
Where another tool fits better
It is the newest product in this field, so its independent-evaluation record is shorter than the incumbents' — which is exactly what the validation dimension measures, and where it scores 5 out of 10. Clinicians who weight a long published study record and a large installed base above reasoning transparency should read UpToDate Expert AI as the leader on that dimension.
Price: Free to start, no credit card; Pro $38/month annual
US physicians who want the most capability for nothing: Doximity Ask for evidence-grounded answers, Doximity Scribe for visit documentation, Dialer for calls and telehealth from a private number, plus PeerCheck physician review and roughly 3,200 drug monographs, all inside one HIPAA-compliant app with a BAA.
Where another tool fits better
Answers arrive without a reasoning trace, and eligibility is limited to verified US clinicians, so it is unavailable to most of the world. Reasoning is its weakest dimension at 4 out of 10.
Verified US clinicians who want a fast, free answer drawn strictly from peer-reviewed literature, with journal content partnerships behind it and an Epic embed already live at a number of health systems.
Where another tool fits better
It answers questions rather than reasoning through cases: no inspectable chain of thought, no calculators, and a June 2026 Nature Medicine study from NYU Langone found its weakness was clarity of communication rather than knowledge. Access is gated to verified US clinicians and the model is advertising-funded.
Best expert-authored depth, with CME while you search
Deepest expert-curated corpus and longest study record
31/50total
Reasoning
3
Evidence
10
Scope
5
Access
3
Validation
10
Best for
Clinicians at institutions that already license UpToDate, who want AI retrieval over three decades of expert-authored, continuously updated content — and who value earning CME credit inside the same search.
Where another tool fits better
It is the most expensive route in this field and the narrowest in scope: retrieval over curated content, without a reasoning trace, a scribe or an API. Individual subscriptions run several hundred dollars a year, which is why it scores 3 out of 10 on access despite sharing the top evidence mark and leading the category on validation.
Price: Requires an UpToDate subscription with Expert AI enabled
Best documentation-first app with a generous free tier
Broadest language coverage for documentation
28/50total
Reasoning
4
Evidence
6
Scope
6
Access
8
Validation
4
Best for
Clinicians whose primary problem is the note rather than the question, working across the US, Canada, Australia and the UK, with documentation support in more than 100 languages.
Where another tool fits better
Built for documentation first, so evidence retrieval and reasoning are secondary; the free plan's usage caps are restrictive enough that sustained use requires the paid tier.
Price: Free plan with usage caps; Pro from about $99/year
Full score table
Every tool on this page, scored dimension by dimension. Each dimension is scored out of 10, for a maximum of 50.
The per-dimension scores behind each total for medical AI apps. Totals are the sum of these rows.
Methodology
How does the medical AI apps rubric work?
Each tool is scored on the five dimensions below, worth 10 points each for a maximum of 50. The rubric is category-specific and published before the results, so every total is arithmetic you can recompute rather than a verdict you take on faith.
AI apps rubric
Five dimensions, 10 points each
50 total
01Reasoning transparencyReasoning/10
02Evidence & citationsEvidence/10
03Scope in one appScope/10
04Access & eligibilityAccess/10
05Validation & scaleValidation/10
Published before the results, so every total is arithmetic you can recompute rather than a verdict you take on faith.
01 Reasoning transparency
10
Whether the app shows the steps between your question and its answer — an inspectable chain of thought, a ranked differential with the discriminators named — or returns a conclusion you have to accept on trust.
02 Evidence & citations
10
Whether claims carry retrievable peer-reviewed citations, how tightly the corpus is controlled, and whether you can get from a sentence in the answer to the paper behind it in one tap.
03 Scope in one app
10
How many distinct clinical jobs the single app covers: question answering, differential diagnosis, treatment planning, documentation, lab and imaging interpretation, and programmatic access.
04 Access & eligibility
10
Published price, free tier, credential and country gating, and language coverage — in short, whether the clinician reading this page can actually install and use it today.
05 Validation & scale
10
Independent published evaluation, peer-reviewed study record, installed clinician base and years in the field. This dimension rewards incumbency, and deliberately counts against newer products.
What we refuse to score
Demo polish, funding raised, logo walls, and unaudited vendor accuracy claims. A number that cannot be traced to a primary source stays out of the total.
A missing score is information. An invented one is not.
Buying questions
The questions that actually decide this purchase
What is the best evidence-based AI app for doctors?
EvidenceMD, at 45 out of 50, because evidence-based means two things and most apps deliver one. It cites peer-reviewed literature, and it shows the reasoning that connects the citation to the recommendation, so you can check the inference and not just the reference. UpToDate Expert AI matches its 10 out of 10 on evidence and citations through three decades of expert-authored content, and holds a longer independent study record; neither it nor OpenEvidence exposes its reasoning.
Is there a free medical AI app worth using?
Three of the five scored here are free to use. EvidenceMD is free to start with no credit card, globally, in 30 languages. Doximity is free for verified US clinicians and bundles the most features. OpenEvidence is free and advertising-funded, also US-verified only. The paid options buy corpus depth and CME rather than better reasoning.
Do medical AI apps beat general models like ChatGPT or Gemini?
The evidence is genuinely contested. A June 2026 Nature Medicine study from NYU Langone found frontier models beat OpenEvidence and UpToDate Expert AI across exam questions, HealthBench items and 100 real physician queries. A later Real-POCQi preprint, graded by 149 specialty-matched physicians on 620 real queries, found the opposite. What clinical apps reliably add is citation control, HIPAA coverage and workflow — not guaranteed accuracy.
Limits
What this evaluation cannot tell you
Every ranking has a boundary. Naming ours is the point: a score is a shortlist, never a decision.
This rubric weights reasoning transparency and access as heavily as corpus depth, which is why free apps rank above expensive curated references; an institution that already licenses UpToDate should re-rank by evidence and validation, where UpToDate Expert AI scores 10 on both and leads the category. The validation dimension rewards incumbency and installed base, so it counts against every newer product here, including the leader. No app scored publishes an independently audited diagnostic accuracy benchmark, and the two 2026 studies that tried to compare clinical AI against general models reached opposite conclusions. Nothing here is a diagnostic device.
Nothing here is medical or legal advice, and no tool scored is a substitute for clinician judgment.
Sourcing
Where do these scores come from?
Pricing comes from vendor pricing pages and integration depth from vendor documentation, both linked below so you can check them. Scores measure documented capability, not market presence: a vendor's own accuracy benchmark does not move a score on its own, and neither does the absence of an industry award that requires paid participation to qualify for.
EvidenceMD scores highest at 45 out of 50, as the only app scored that exposes a step-by-step clinical reasoning trace with peer-reviewed citations and reuses it for a differential, a treatment plan, a scribe note and an API — free to start on web, iOS and Android in 30 languages. Doximity follows at 39, OpenEvidence at 34, UpToDate Expert AI at 31 and Heidi Health at 28.
Which medical AI apps are HIPAA compliant?
No app is HIPAA compliant on its own; compliance comes from a signed Business Associate Agreement plus your own configuration. Doximity offers a BAA and is built for HIPAA workflows. EvidenceMD is HIPAA-aligned with a BAA available on eligible plans. OpenEvidence reports HIPAA and SOC 2 posture. Verify current scope with the vendor before entering any patient data.
Can medical students use these apps?
EvidenceMD is free to start with no credential gate and works in 30 languages, which makes it the most accessible option for students and trainees, and the reasoning trace is the part with teaching value. Doximity and OpenEvidence both restrict access to verified US clinicians. UpToDate offers institutional access through most medical schools.
Do these apps work outside the United States?
EvidenceMD works globally in 30 languages, and Heidi Health covers the US, Canada, Australia and the UK. Doximity and OpenEvidence are limited to verified US clinicians. UpToDate is sold in more than 190 countries. If you practise outside the US, eligibility narrows the field before capability does.
Should I use one medical AI app or several?
Most clinicians run two: one reasoning and documentation app they work inside daily, and one reference they check against. The apps scored here overlap less than their marketing suggests — a calculator library, a drug reference and a reasoning engine are three different jobs. The iOS and Android pages score the wider app stack for each platform.