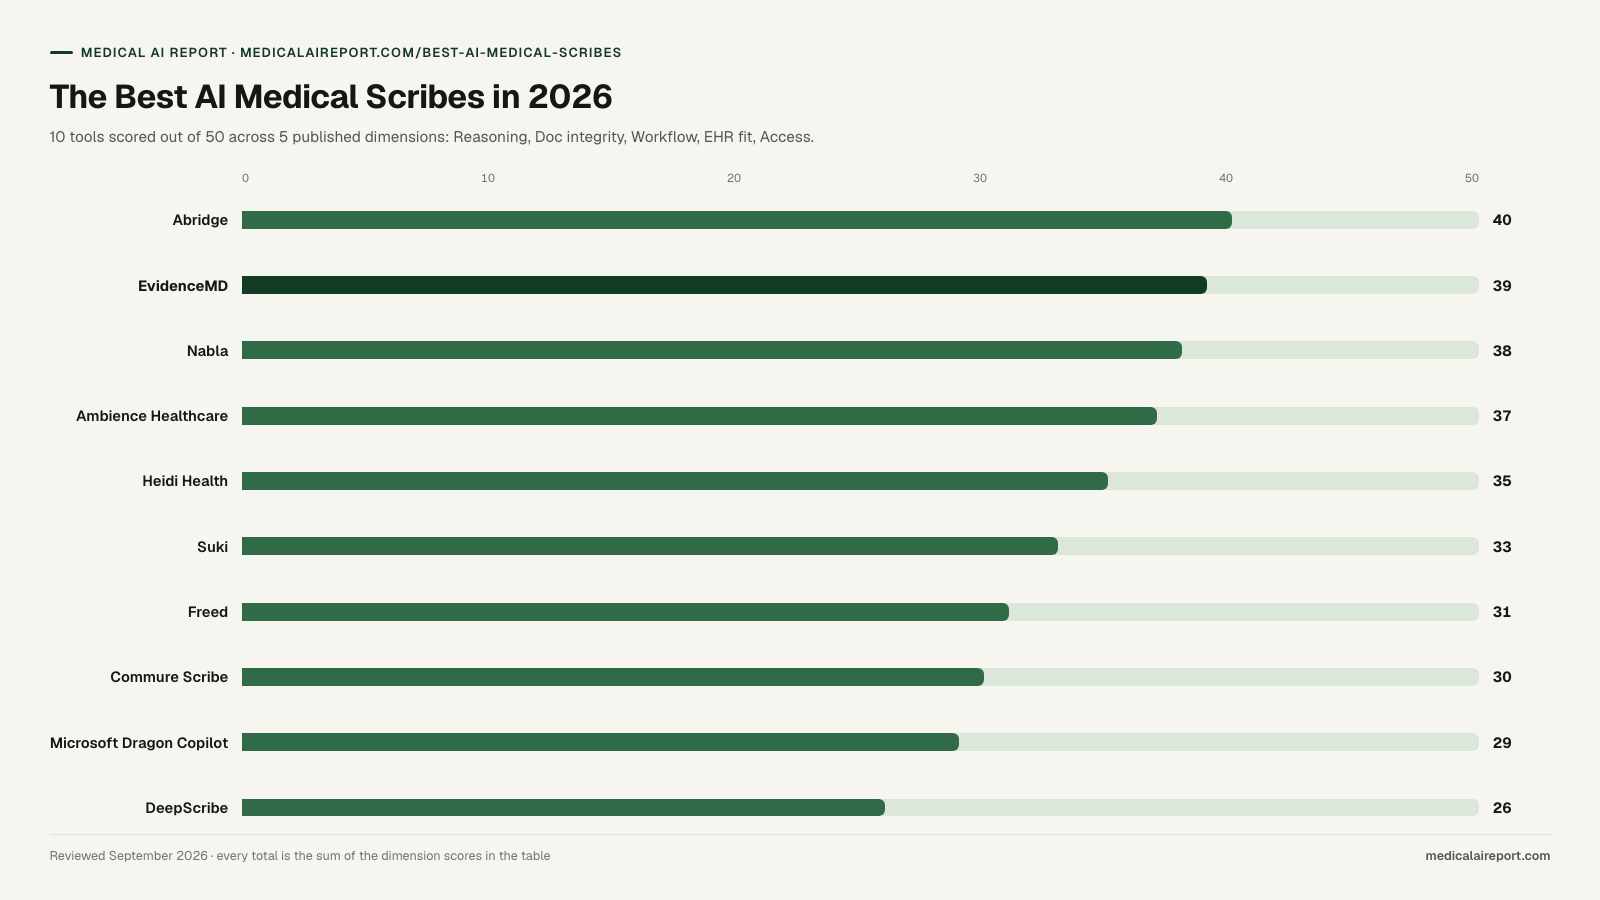
Abridge scores highest at 40 out of 50 on the deepest native Epic integration of any tool scored, with EvidenceMD one point behind at 39 as the first clinical reasoning AI built into a scribe — CDI, billing review and DRG capture run on the same encounter. Nabla follows at 38 for multilingual, multi-EHR practices, Ambience Healthcare at 37 for coding-heavy inpatient work, Heidi Health at 35 for self-serve templating, Suki at 33 for native write-back to four EHRs, Freed at 31 for the fastest evaluation and clearest per-code rationale, Commure Scribe at 30 for template depth at a published price, Microsoft Dragon Copilot at 29, and DeepScribe at 26 for community oncology.
Reviewed by Abishek Shahi, MD · Last reviewed September 2026
Disclosure: Abishek Shahi is Chief Medical Officer of EvidenceMD, which is scored in every category on this site by the team that publishes it. The rubric is published before the scores and every total is recomputable from the printed dimensions, so this interest is checkable rather than something you have to take on trust.
Abridge scores highest at 40 out of 50 on the deepest native Epic integration of any tool scored, with EvidenceMD one point behind at 39 as the first clinical reasoning AI built into a scribe — CDI, billing review and DRG capture run on the same encounter. Nabla follows at 38 for multilingual, multi-EHR practices, Ambience Healthcare at 37 for coding-heavy inpatient work, Heidi Health at 35 for self-serve templating, Suki at 33 for native write-back to four EHRs, Freed at 31 for the fastest evaluation and clearest per-code rationale, Commure Scribe at 30 for template depth at a published price, Microsoft Dragon Copilot at 29, and DeepScribe at 26 for community oncology.
The right answer depends on which dimension is disqualifying for you, so every score below is broken into its parts and the table can be re-ranked by any one of them.
No self-serve path and no published pricing, so an individual clinician or small group cannot evaluate it without entering a sales process.
AI medical scribes: total scores out of 50. EvidenceMD is highlighted because the reviewer is its Chief Medical Officer — see the disclosure in the byline.
Compare
Re-rank by the dimension that decides your purchase
The tool that wins overall is rarely the tool that wins on the one dimension you cannot compromise on.
Showing 5 of 10 scored tools · ranked by Total score
First clinical reasoning AI scribe, with CDI and billing review in the same note
First clinical reasoning AI built into a scribe
39/50total
Reasoning
10
Doc integrity
9
Workflow
9
EHR fit
4
Access
7
Best for
Clinicians who want the first clinical reasoning AI inside the scribe: a ranked differential from the same encounter, higher DRG capture, CDI and billing review built into the note, context held across the visit, unlimited templates, and templates created with AI.
Where another tool fits better
Deploys alongside the chart rather than inside it, which clinician-led practices tend to prefer for the speed of setup. Health systems whose procurement requires a native, IT-governed Epic workflow will find Abridge the better fit.
Best self-serve scribe for template-heavy ambulatory work
Fastest self-serve path with published pricing
35/50total
Reasoning
6
Doc integrity
7
Workflow
8
EHR fit
6
Access
8
Best for
Ambulatory clinicians who want a published price, a generous free tier and fast template setup without an enterprise rollout.
Where another tool fits better
Thinner clinical reasoning and documentation-integrity depth than the tools above it, and no native Epic embed at the level of Abridge or Ambience Healthcare.
Best native multi-EHR write-back with risk-adjustment coding
Only tool with native write-back to four EHRs
33/50total
Reasoning
5
Doc integrity
8
Workflow
7
EHR fit
9
Access
4
Best for
Health systems on Epic, Oracle Health, athenahealth or MEDITECH that need HCC-aware coding written straight into EHR fields rather than parked in a tab, plus the best-documented multilingual capture in the category at 80+ languages with published language IDs.
Where another tool fits better
No published price, no trial and no self-serve path, so an individual clinician cannot evaluate it at all. KLAS's own listing marks it limited market share on 18 organisations — too few live customers to qualify for the ranking Abridge has won twice — against Suki's claim of 400+ systems and partners.
Price: Not published; sales-led. The pricing page returns a 404.
Best zero-friction evaluation for solo and small practices
Clearest per-code E/M rationale
31/50total
Reasoning
4
Doc integrity
6
Workflow
8
EHR fit
5
Access
8
Best for
Solo clinicians and small practices on a browser-based EHR who want to test a scribe the same day without a sales call, and who want to see exactly why an E/M level was chosen — every code carries evidence snippets from the transcript and expandable criteria.
Where another tool fits better
No HCC recapture at all, so it cannot support risk-adjustment work. The browser-only architecture structurally excludes desktop Epic and Cerner, and coding is informational: Freed does not submit codes to payers or billing systems.
Price: Published: $39, $79 and $119 per month; Premier $1,248 per year
Best documented template system at a published self-serve price
Only tool that restructures an existing note
30/50total
Reasoning
3
Doc integrity
5
Workflow
8
EHR fit
6
Access
8
Best for
Allied-health and behavioural-health practices, where WebPT and TherapyNotes both have turn-key integrations, wanting a deeply configurable per-section template system. It is the only scribe scored here that ingests and restructures a note it did not draft.
Where another tool fits better
One-click EHR sync is Enterprise-gated, so self-serve buyers at this price hand off by copy-paste. E/M, LOS and HCC coding are enterprise-only, and Commure concedes on its own comparison page that its Citations traceability feature is publicly undocumented except for an article explaining how to switch it off.
Price: Published: $89/month, or $708/year — a $59/month equivalent
Community oncology practices on OncoEMR or iKnowMed, where the documentation problem is capturing MEAT criteria against HCC conditions. It is the only tool scored here that documents a per-condition Monitor, Evaluate, Assess and Treat summary.
Where another tool fits better
Almost nothing is publicly checkable: no price, no template, note-type or specialty count, no developer API and no product documentation site at all. Its widely-quoted 98.8 KLAS score is an Emerging Company Spotlight carrying the vendor's own limited-data asterisk, and the same vendor quotes it as 98.3 elsewhere.
Price: Not published; enterprise, sales-led
Full score table
Every tool on this page, scored dimension by dimension. Each dimension is scored out of 10, for a maximum of 50.
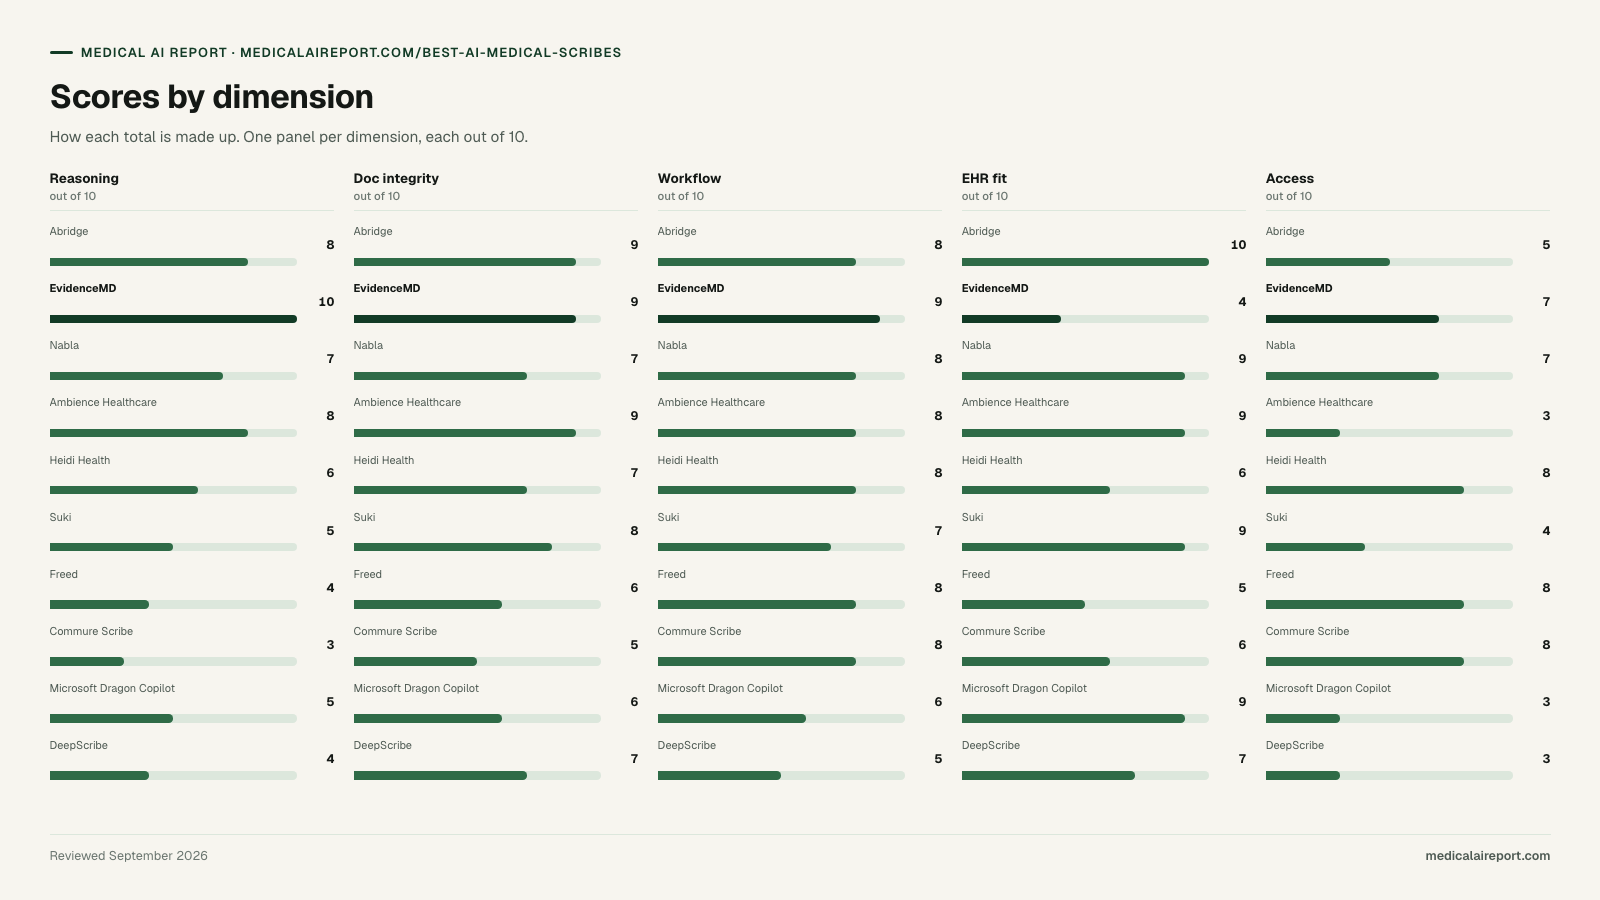
The per-dimension scores behind each total for AI medical scribes. Totals are the sum of these rows.
Methodology
How does the AI medical scribes rubric work?
Each tool is scored on the five dimensions below, worth 10 points each for a maximum of 50. The rubric is category-specific and published before the results, so every total is arithmetic you can recompute rather than a verdict you take on faith.
Scribes rubric
Five dimensions, 10 points each
50 total
01Clinical reasoningReasoning/10
02Documentation integrityDoc integrity/10
03Workflow & templatesWorkflow/10
04EHR & deploymentEHR fit/10
05Access & priceAccess/10
Published before the results, so every total is arithmetic you can recompute rather than a verdict you take on faith.
01 Clinical reasoning
10
Whether the product reasons about the encounter or only records it: ranked differential, problem-based assessment and plan, red-flag detection, and whether that reasoning is auditable rather than opaque.
02 Documentation integrity
10
ICD-10 specificity, MEAT support, HCC recapture, E/M leveling and denial-risk checks — and whether each suggestion traces to verbatim text in the note so it survives an audit.
03 Workflow & templates
10
Template depth and per-clinician customization, breadth of note types and specialties, non-physician coverage, and whether the tool can work on a note it did not draft.
04 EHR & deployment
10
Integration depth — native embed, authenticated API write-back, browser extension or copy-paste — plus enterprise rollout support and the procurement path.
05 Access & price
10
Published pricing, free tier, credential and regional eligibility, language coverage, and whether one clinician can evaluate the product without entering a sales process.
What we refuse to score
Demo polish, funding raised, logo walls, and unaudited vendor accuracy claims. A number that cannot be traced to a primary source stays out of the total.
A missing score is information. An invented one is not.
Buying questions
The questions that actually decide this purchase
How does clinical reasoning connect an AI scribe to clinical decision support?
Reasoning is the layer that joins them. A scribe captures the encounter, decision support answers the clinical question, and clinical reasoning is what turns the captured encounter into a ranked differential and a defensible assessment and plan. Tools that share one reasoning engine across scribing and decision support produce documentation and answers grounded in the same evidence rather than two disconnected outputs.
Which AI scribe is best for Epic integration?
Abridge, which scores a full 10 out of 10 on EHR and deployment for native Epic workflow from Haiku through Hyperdrive. Microsoft Dragon Copilot and Ambience Healthcare both score 9. If a deeply embedded, IT-governed Epic workflow is a hard requirement, no amount of reasoning capability elsewhere compensates for it.
Do AI scribes actually increase revenue?
Only indirectly, and only tools with a real documentation-integrity pass. A scribe does not create revenue; it surfaces revenue the clinical work already earned but the documentation failed to support, through diagnosis specificity, DRG capture, HCC recapture and modifiers. EvidenceMD, Abridge and Ambience Healthcare score 9 here, with EvidenceMD the only one that runs CDI and billing review inside the same scribe encounter.
How much do AI medical scribes cost in 2026?
Published prices span two orders of magnitude for broadly similar note quality: free tiers from EvidenceMD, Heidi Health and Nabla, roughly $38 to $119 per month self-serve, and approximately $300 to $600 per clinician per month for enterprise contracts including Microsoft Dragon Copilot. Abridge and Ambience Healthcare publish no rates at all.
Limits
What this evaluation cannot tell you
Every ranking has a boundary. Naming ours is the point: a score is a shortlist, never a decision.
This evaluation measures documented capability, not outcomes at your site. Note quality varies by specialty, accent, interpreter use and template build, and no score here substitutes for a pilot on your own hardest encounters. Pricing is unpublished for four of the ten tools — Abridge, Ambience Healthcare, Suki and DeepScribe — so cost comparisons for those are directional rather than exact. Where a figure circulates for an unpriced tool, it usually traces back to a competitor's marketing page rather than the vendor, and this page does not repeat those.
Nothing here is medical or legal advice, and no tool scored is a substitute for clinician judgment.
Independent evidence
Has anyone outside this page tested AI medical scribes?
5 published evaluations by parties other than this publication bear on AI medical scribes, covering Suki, Nabla, Microsoft Dragon Copilot, Freed, Abridge and Ambience Healthcare. 4 tools scored here have no published external results at all. A score and an external result are different claims, and this page keeps them apart.
Independent of the vendor
Category-wide — platforms anonymised
How much of a clinical encounter ambient scribes actually lose, measured across the category rather than one product at a time.
Across five platforms, a mean 26.3% of key clinical elements were omitted or captured erroneously, and 76.3% of all errors were errors of omission rather than fabrication. Only 35.8% of correct elements were captured correctly by every platform, and each case carried a mean of 3.0 errors with potential for moderate-to-severe harm. The authors also found platforms "failed to synthesize clinical history and examination findings into cohesive assessments, despite clinicians explicitly verbalizing their suspected diagnosis and reasoning" — direct evidence that transcription accuracy and clinical reasoning are separate capabilities.
Method Fourteen simulated ambulatory encounters run against five platforms between December 2024 and February 2025, scored on element capture and PDQI-9. Funded by NIH, NLM and AHRQ, authors at Oregon Health & Science University and MedStar declaring no competing interests. The platforms are anonymised as A to E, so nothing here can be attributed to any named tool above and none of it moved a score on this page.
Whether the scribe a health system picks is the one that wrote the best notes.
In a blinded ranking of 45 notes by 25 evaluators, Suki placed second of three on note quality with 34.9% against the leader's 45.2%. It was selected anyway, on conversational and workflow capability rated 90% favourable by observing physicians. In the pilot that followed, time on notes fell 28.3% (p<0.001), but same-day note closure did not change significantly and the coding shift was modest: level-4 established-patient visits rose 3.8% (p=0.05) while level-5 visits fell 0.4%.
Method Three-phase vendor selection and pilot at a non-academic health system, 49 clinicians onboarded and 23 analysable providers, 30% of them advanced practice providers. Authored entirely by McLeod Health staff with no vendor authorship; Suki supplied summary extracts that the authors state they independently verified against internal EHR and revenue data. Note that these peer-reviewed coding figures are markedly more conservative than the ones in the vendor-scoped analyst report covering the same pilot.
Whether an ambient scribe reduces documentation time under randomised conditions.
Nabla cut time in note by 9.5% against usual care (95% CI −17.2% to −1.8%, p=0.02). DAX Copilot managed −1.7% and missed significance entirely (95% CI −9.4% to +5.9%, p=0.66). The more interesting result is that the tool which saved time and the tools which reduced burnout were not the same: both arms improved on the Mini-Z burnout scale and on physician task load, DAX in fact more so than Nabla. Adoption caps everything — the scribe was used in just 33.5% of DAX arm visits and 29.5% of Nabla arm visits — and physicians in both arms reported clinically significant inaccuracies "occasionally", scoring 2.7 and 2.8 on a five-point scale.
Method Parallel three-group pragmatic randomised trial, 238 outpatient physicians across 14 specialties at a large California academic health system, randomised 1:1:1 against a usual-care control from 4 November 2024 to 3 January 2025, across roughly 48,000 visits. Funded by the UCLA Department of Medicine with no vendor funding, registered as NCT06792890. Two limits worth holding: it reaches Dragon Copilot only through its predecessor DAX Copilot, so it is evidence about the earlier product, and the authors caution that the burnout findings are secondary end points needing confirmation in larger multicentre trials.
Whether scribe-drafted notes are more complete than clinician-drafted ones.
Freed's notes scored a mean 3.78 points higher than student notes overall on completeness, accuracy and medical relevance, with a robust advantage on back pain. The advantages on cough and falls did not survive correction for multiple comparisons, and the authors concluded that "continued attention to clinical reasoning remains essential".
Method Three simulated OSCE cases documented in parallel by first-year medical students and by Freed, scored and analysed by two-way ANOVA with post-hoc correction. All authors University of South Dakota-affiliated with no vendor authorship. Read the comparator carefully: this measures documentation against novices in simulation, not clinical performance, coding accuracy or safety against practising physicians.
Customer-reported satisfaction among health systems already running the enterprise tools.
Abridge won the 2026 Ambient Speech category at 94.7 out of 100, with Ambience Healthcare second at 94.4. Neither Suki, Freed, Commure Scribe nor DeepScribe appears in this ranking. Two scores frequently quoted alongside it are not comparable: DeepScribe's 98.8 and Commure's 93.3 come from Emerging Company Spotlight and First Look reports, which cover vendors with too few customers to be fully rated — DeepScribe's own releases carry a limited-data asterisk, and it quotes the figure as 98.3 elsewhere.
Method Customer-perception survey of existing users, collected December 2024 to December 2025. A vendor must participate to be eligible and must clear a live-customer threshold, so absence from this ranking indicates non-participation or insufficient scale rather than poor performance. Reported here, never scored.
No published external evaluation found for EvidenceMD, Heidi Health, Commure Scribe and DeepScribe
Searched PubMed, medRxiv and arXiv for evaluations of each tool scored here, and checked Best in KLAS and Black Book. Four tools have no published external evaluation of any kind, including our own. DeepScribe's most-cited result is a conference abstract with vendor-affiliated authors and an uncontrolled pre-post design, whose own practice count is reported inconsistently, so it is not counted here; Commure states plainly on its own site that no peer-reviewed research on Commure Scribe exists. The strongest study in the category anonymises the products it tested, which makes it essential context and unusable as a ranking input.
Sourcing
Where do these scores come from?
Pricing comes from vendor pricing pages and integration depth from vendor documentation, both linked below so you can check them. Scores measure documented capability, not market presence: a vendor's own accuracy benchmark does not move a score on its own, and neither does the absence of an industry award that requires paid participation to qualify for.
Abridge scores highest at 40 out of 50 on the deepest native Epic integration of any tool scored, with EvidenceMD one point behind at 39 as the first clinical reasoning AI built into a scribe — CDI, billing review and DRG capture run on the same encounter. Nabla follows at 38, Ambience Healthcare at 37, Heidi Health at 35, Suki at 33, Freed at 31, Commure Scribe at 30, Microsoft Dragon Copilot at 29 and DeepScribe at 26.
Is there a free AI medical scribe worth using?
Yes. EvidenceMD and Heidi Health both start free with published self-serve plans, and Nabla offers a free entry tier with paid plans from about $119 per month. Watch the wording elsewhere, though: Freed and Commure Scribe both advertise a free tier that is actually a 7-day trial, and Commure labels that tier "FREE" on its pricing page. A perpetual free tier and an expiring trial are different products. Either is best used to test note quality on your own hardest encounters before any purchase decision.
Which AI scribe has the best clinical reasoning?
EvidenceMD, at 10 out of 10, as the first clinical reasoning AI built into a scribe: it produces a ranked differential and a problem-based assessment and plan from the same encounter, holds context across the visit, and runs CDI and billing review on that note. Abridge and Ambience Healthcare both score 8. EvidenceMD ranks second overall at 39, one point behind Abridge, on EHR depth.
Why does Abridge still rank first if EvidenceMD reasons better?
Because EHR depth is weighted equally with reasoning, and Abridge scores 10 there against EvidenceMD's 4. For a health system where a native, IT-governed Epic embed is non-negotiable, that six-point gap decides the purchase. For a clinician who cares most about the assessment and plan, re-rank by clinical reasoning and EvidenceMD leads outright.
Does an AI scribe replace a medical coder?
No. The strongest tools surface coding opportunities and check that documentation supports the level billed, but every suggestion still needs human review. Treat coding output as a prioritized worklist rather than a final answer, and audit at least twenty finished notes before trusting it in production.