Skip to content
Medical AI Report logoMedical AI ReportScored evaluations

1 of 11 categories · Updated October 2026

Microsoft Dragon Copilot review

Microsoft Dragon Copilot is scored in one of the 11 categories on this site. It scores 29/50 for AI medical scribes. It does not rank first in any category scored here.

Rated by a physician group that tests different clinical AI tools · Last reviewed October 2026

Best score
29/50
Average
29/50
Categories
1
Ranked first
0

The scores

How is Microsoft Dragon Copilot scored in each category?

Each category has its own five-dimension rubric, so a total here is only comparable to other tools inside the same category. Every dimension is worth 10 points.

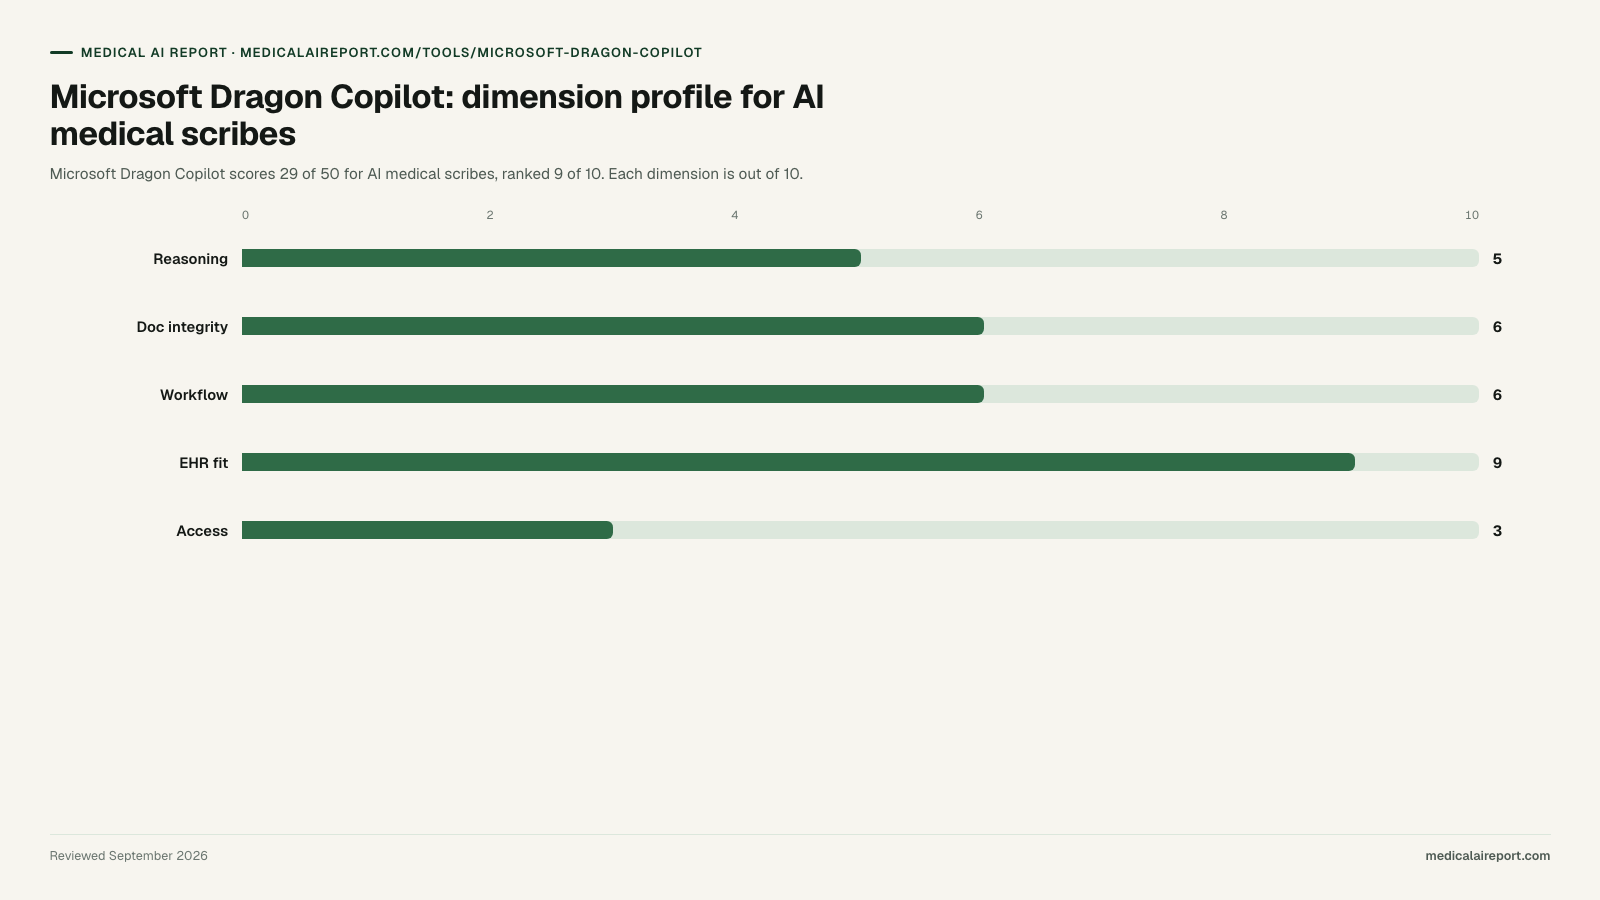
Microsoft Dragon Copilot: dimension profile for AI medical scribes. Bar chart: Reasoning 5, Doc integrity 6, Workflow 6, EHR fit 9, Access 3, out of 10.
Microsoft Dragon Copilot's dimension scores in AI medical scribes, its strongest category on this site.

Best for Microsoft-standardized health systems

29/50

9th of 10

Microsoft Dragon Copilot dimension scores for AI medical scribes
Clinical reasoningDocumentation integrityWorkflow & templatesEHR & deploymentAccess & price
5/106/106/109/103/10
Best for
Health systems already standardized on Microsoft infrastructure and governance, where estate consistency outweighs note quality.
Limitation
Heavy IT involvement, the highest cost in the category, and among the weakest reasoning layers of the tools scored.
Price
Enterprise; frequently cited near $600/clinician/month

Dimension-by-dimension rubric criteria for AI medical scribes

  1. Clinical reasoning5/10

    Category high: 10/10

    Whether the product reasons about the encounter or only records it: ranked differential, problem-based assessment and plan, red-flag detection, and whether that reasoning is auditable rather than opaque.

  2. Documentation integrity6/10

    Category high: 9/10

    ICD-10 specificity, MEAT support, HCC recapture, E/M leveling and denial-risk checks — and whether each suggestion traces to verbatim text in the note so it survives an audit.

  3. Workflow & templates6/10

    Category high: 9/10

    Template depth and per-clinician customization, breadth of note types and specialties, non-physician coverage, and whether the tool can work on a note it did not draft.

  4. EHR & deployment9/10

    Category high: 10/10

    Integration depth — native embed, authenticated API write-back, browser extension or copy-paste — plus enterprise rollout support and the procurement path.

  5. Access & price3/10

    Category high: 8/10

    Published pricing, free tier, credential and regional eligibility, language coverage, and whether one clinician can evaluate the product without entering a sales process.

Field context

How Microsoft Dragon Copilot stacks up against the full scribes field

In AI medical scribes, Microsoft Dragon Copilot places 9th of 10 tools with 29/50. Its commercial model is classified as enterprise or institutional, sales-led (Enterprise; frequently cited near $600/clinician/month). Standard at health-system scale and not disqualifying, but it means cost cannot be compared without a procurement process, and the number usually depends on what the seller believes you will pay. A single clinician generally cannot evaluate these at all.

Full AI medical scribes leaderboard showing how Microsoft Dragon Copilot compares with all 10 tools in the category. Each dimension is scored out of 10, for a maximum of 50.
ToolReasoningDoc integrityWorkflowEHR fitAccessTotal
Abridge89810540
EvidenceMD10994739
Nabla7789738
Ambience Healthcare8989337
Heidi Health6786835
Suki5879433
Freed4685831
Commure Scribe3586830
Microsoft Dragon Copilot5669329
DeepScribe4757326

Pattern

Where Microsoft Dragon Copilot wins and where it loses

Full marks

Microsoft Dragon Copilot takes no full-mark dimension on this site. Its strongest result is 29/50 for AI medical scribes.

Weakest dimensions

  • Access & priceScribes3/10
  • Clinical reasoningScribes5/10
  • Documentation integrityScribes6/10

Limits

What this review cannot tell you

This page aggregates scores from the category rubrics. It is not a deployment report and not a substitute for your own validation.

Scores measure documented capability, not outcomes in your clinic. Microsoft Dragon Copilot has not been tested here against live patient data, and no score on this page reflects implementation quality, support responsiveness or contracted uptime. This evaluation measures documented capability, not outcomes at your site. Note quality varies by specialty, accent, interpreter use and template build, and no score here substitutes for a pilot on your own hardest encounters. Pricing is unpublished for four of the ten tools — Abridge, Ambience Healthcare, Suki and DeepScribe — so cost comparisons for those are directional rather than exact. Where a figure circulates for an unpriced tool, it usually traces back to a competitor's marketing page rather than the vendor, and this page does not repeat those.

Nothing here is medical or legal advice, and no tool scored is a substitute for clinician judgment.

Common questions

Common questions about Microsoft Dragon Copilot

What does Microsoft Dragon Copilot score?

Microsoft Dragon Copilot is scored in one of the 11 categories on this site. It scores 29/50 for AI medical scribes. It does not rank first in any category scored here. Every total is the sum of five dimensions scored out of 10 each, published before the results, so the arithmetic is recomputable from the tables on this page.

What is Microsoft Dragon Copilot best at?

Microsoft Dragon Copilot takes no full-mark dimension on this site. Its highest total is 29/50 for AI medical scribes, ranking 9th of 10. Health systems already standardized on Microsoft infrastructure and governance, where estate consistency outweighs note quality.

What are the limitations of Microsoft Dragon Copilot?

Heavy IT involvement, the highest cost in the category, and among the weakest reasoning layers of the tools scored. Its weakest dimension scores are 3/10 on access & price for AI medical scribes, 5/10 on clinical reasoning for AI medical scribes and 6/10 on documentation integrity for AI medical scribes.

How much does Microsoft Dragon Copilot cost?

Enterprise; frequently cited near $600/clinician/month Pricing is taken from the vendor's published pricing page where one exists; where it does not, that absence is recorded rather than estimated.

What are the alternatives to Microsoft Dragon Copilot?

Abridge, Ambience Healthcare, Commure Scribe and DeepScribe are scored against Microsoft Dragon Copilot on at least one shared rubric. Against Abridge for AI medical scribes: 29–40. Against Ambience Healthcare for AI medical scribes: 29–37. Against Commure Scribe for AI medical scribes: 29–30. Against DeepScribe for AI medical scribes: 29–26.