Best zero-friction evaluation for solo and small practices
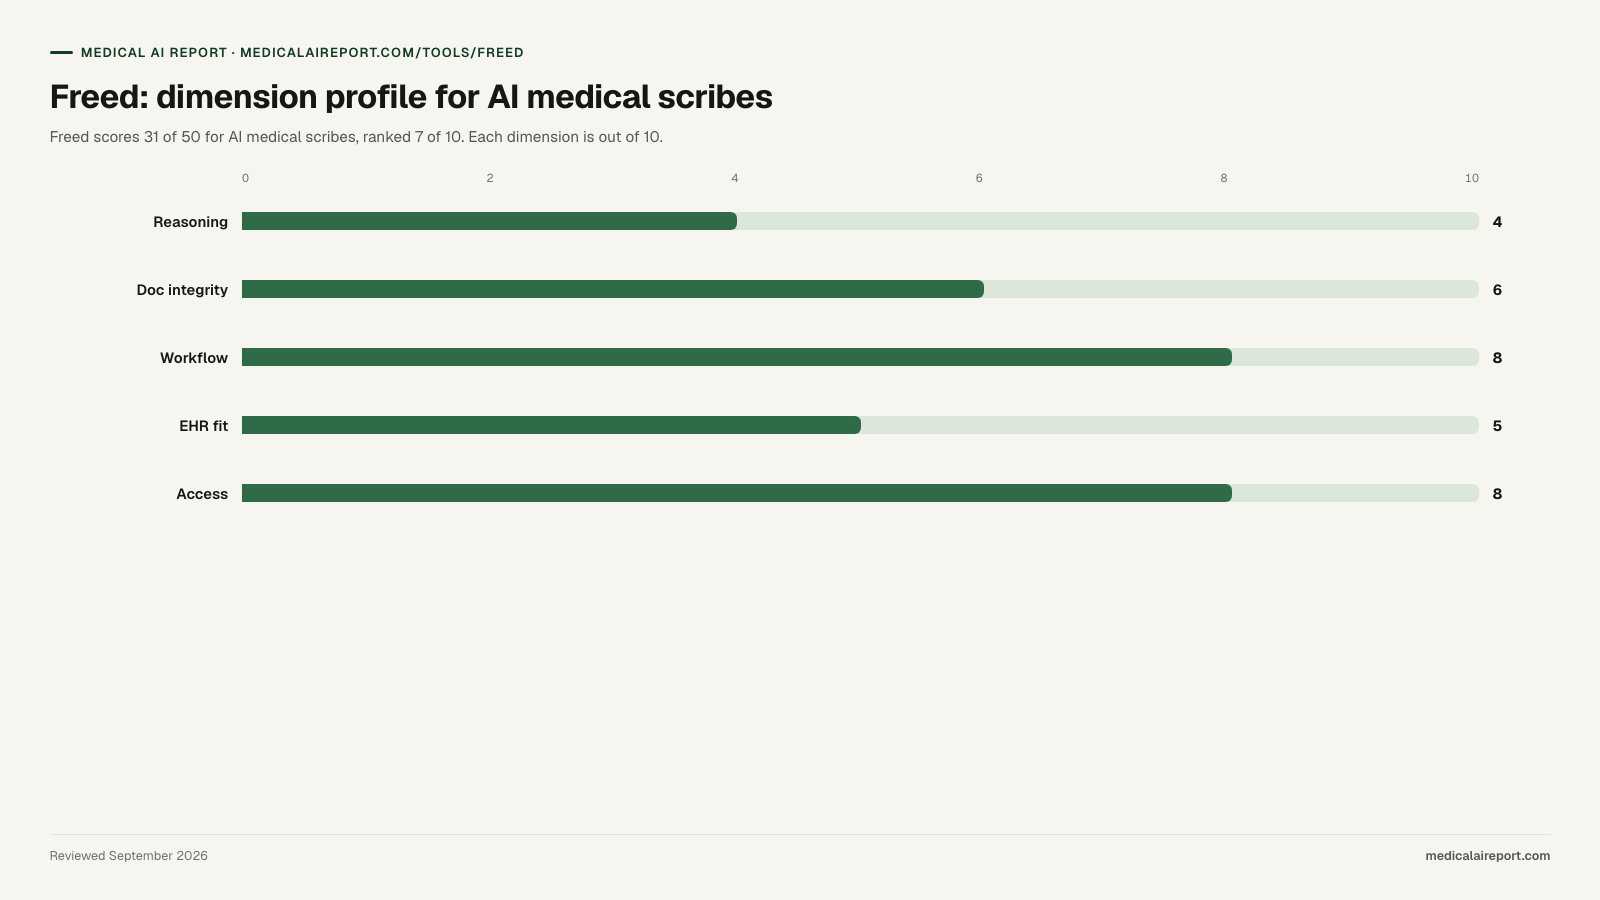
31/50
7th of 10
| Clinical reasoning | Documentation integrity | Workflow & templates | EHR & deployment | Access & price |
|---|---|---|---|---|
| 4/10 | 6/10 | 8/10 | 5/10 | 8/10 |
- Best for
- Solo clinicians and small practices on a browser-based EHR who want to test a scribe the same day without a sales call, and who want to see exactly why an E/M level was chosen — every code carries evidence snippets from the transcript and expandable criteria.
- Limitation
- No HCC recapture at all, so it cannot support risk-adjustment work. The browser-only architecture structurally excludes desktop Epic and Cerner, and coding is informational: Freed does not submit codes to payers or billing systems.
- Price
- Published: $39, $79 and $119 per month; Premier $1,248 per year
Dimension-by-dimension rubric criteria for AI medical scribes
- Clinical reasoning4/10
Category high: 10/10
Whether the product reasons about the encounter or only records it: ranked differential, problem-based assessment and plan, red-flag detection, and whether that reasoning is auditable rather than opaque.
- Documentation integrity6/10
Category high: 9/10
ICD-10 specificity, MEAT support, HCC recapture, E/M leveling and denial-risk checks — and whether each suggestion traces to verbatim text in the note so it survives an audit.
- Workflow & templates8/10
Category high: 9/10
Template depth and per-clinician customization, breadth of note types and specialties, non-physician coverage, and whether the tool can work on a note it did not draft.
- EHR & deployment5/10
Category high: 10/10
Integration depth — native embed, authenticated API write-back, browser extension or copy-paste — plus enterprise rollout support and the procurement path.
- Access & price8/10
Category high: 8/10
Published pricing, free tier, credential and regional eligibility, language coverage, and whether one clinician can evaluate the product without entering a sales process.