Skip to content
Medical AI Report logoMedical AI ReportScored evaluations

1 of 11 categories · Updated October 2026

General frontier LLMs under BAA review

General frontier LLMs under BAA is scored in one of the 11 categories on this site. It scores 27/50 for clinical reasoning AI. It does not rank first in any category scored here.

Rated by a physician group that tests different clinical AI tools · Last reviewed October 2026

Best score
27/50
Average
27/50
Categories
1
Ranked first
0

The scores

How is General frontier LLMs under BAA scored in each category?

Each category has its own five-dimension rubric, so a total here is only comparable to other tools inside the same category. Every dimension is worth 10 points.

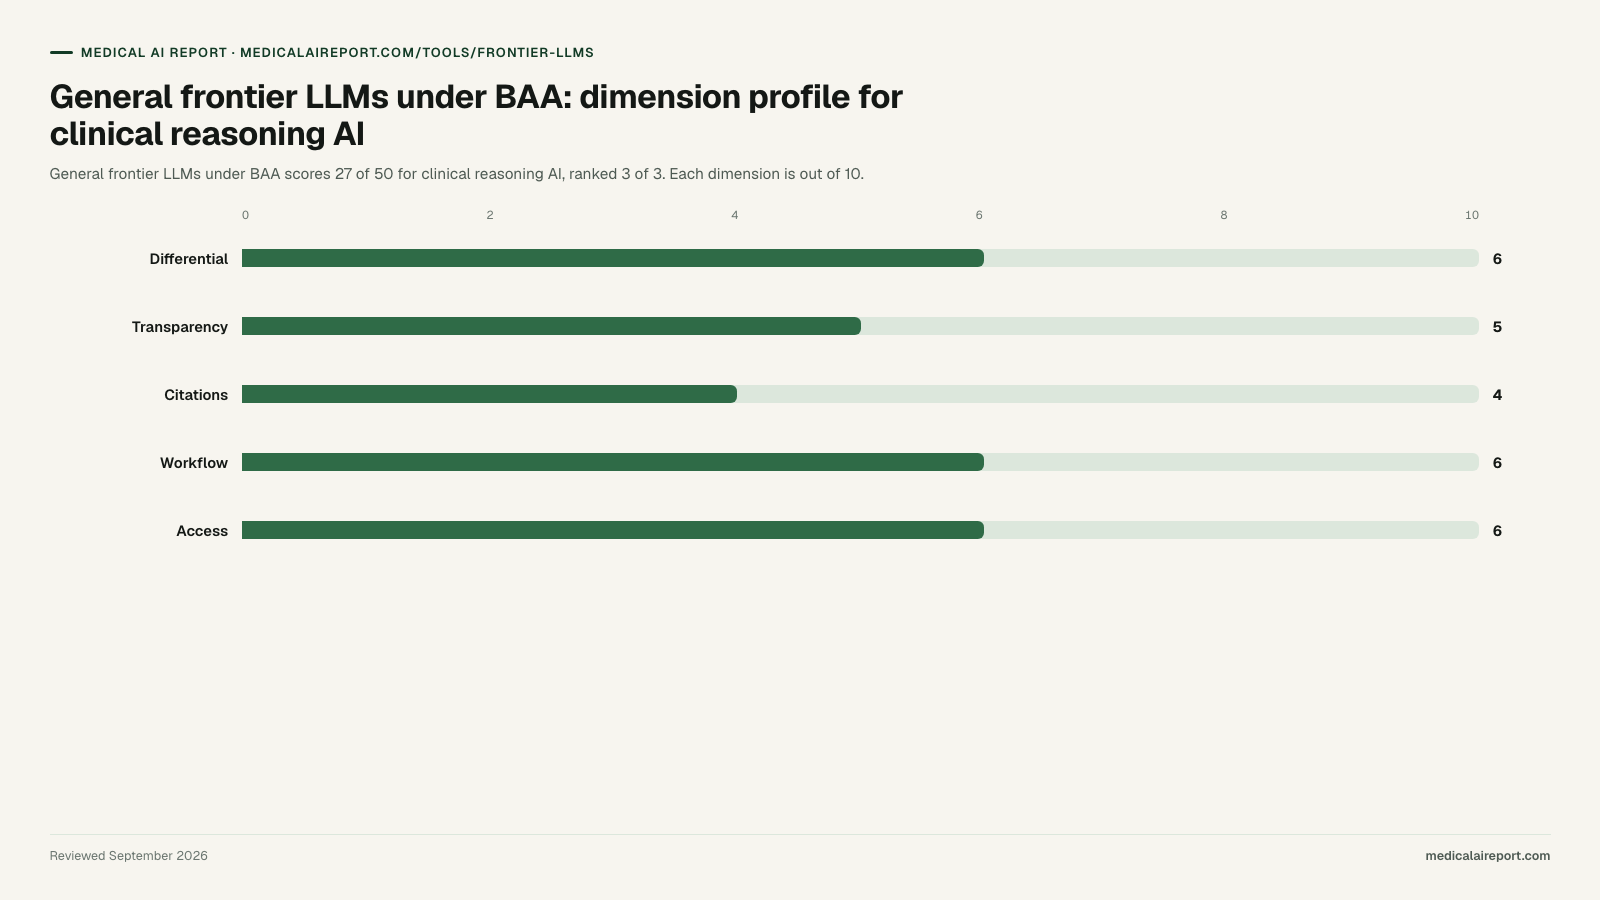
General frontier LLMs under BAA: dimension profile for clinical reasoning AI. Bar chart: Differential 6, Transparency 5, Citations 4, Workflow 6, Access 6, out of 10.
General frontier LLMs under BAA's dimension scores in clinical reasoning AI, its strongest category on this site.

Flexible, but you build the clinical layer

27/50

7th of 7

General frontier LLMs under BAA dimension scores for clinical reasoning AI
Differential qualityReasoning transparencyEvidence & citationsWorkflow integrationAccess & eligibility
6/105/104/106/106/10
Best for
Teams prototyping their own reasoning workflow who want full control over prompts, retrieval and output structure.
Limitation
No clinical grounding by default and unreliable citation of primary literature, so hallucinated references are a live risk. Consumer tiers sign no BAA and cannot touch PHI.
Price
Per-token pricing; BAA required for any PHI

Dimension-by-dimension rubric criteria for clinical reasoning AI

  1. Differential quality6/10

    Category high: 9/10

    Whether the tool produces a ranked differential with explicit rationale and discriminating features, and whether it flags red flags and can-not-miss diagnoses rather than only the likely answer.

  2. Reasoning transparency5/10

    Category high: 10/10

    Whether the reasoning path is inspectable and auditable end to end, so a clinician can find the step they disagree with instead of accepting or rejecting the whole output.

  3. Evidence & citations4/10

    Category high: 10/10

    Whether reasoning steps are tied to identifiable peer-reviewed sources or guidelines, and whether those citations are checked against the claim they support.

  4. Workflow integration6/10

    Category high: 7/10

    Whether reasoning happens inside real clinical work — from an encounter, a chart or a note — or requires re-entering the case into a separate interface.

  5. Access & eligibility6/10

    Category high: 9/10

    Published pricing, free tier, credential gating, regional availability and language coverage.

Field context

How General frontier LLMs under BAA stacks up against the full clinical reasoning field

In clinical reasoning AI, General frontier LLMs under BAA places 7th of 7 tools with 27/50. Its commercial model is classified as published subscription (Per-token pricing; BAA required for any PHI). Rare enough in clinical AI to be a signal in itself. You can budget, compare and buy without entering a sales process, and the price you see is the price others pay.

Full Clinical reasoning AI leaderboard showing how General frontier LLMs under BAA compares with all 7 tools in the category. Each dimension is scored out of 10, for a maximum of 50.
ToolDifferentialTransparencyCitationsWorkflowAccessTotal
EvidenceMD91097944
Isabel DDx Companion9676735
DynaMed75106634
OpenEvidence6397833
DXplain8665530
UpToDate Expert AI43107428
General frontier LLMs under BAA6546627

Pattern

Where General frontier LLMs under BAA wins and where it loses

Full marks

General frontier LLMs under BAA takes no full-mark dimension on this site. Its strongest result is 27/50 for clinical reasoning AI.

Weakest dimensions

  • Evidence & citationsClinical reasoning4/10
  • Reasoning transparencyClinical reasoning5/10
  • Differential qualityClinical reasoning6/10

Limits

What this review cannot tell you

This page aggregates scores from the category rubrics. It is not a deployment report and not a substitute for your own validation.

Scores measure documented capability, not outcomes in your clinic. General frontier LLMs under BAA has not been tested here against live patient data, and no score on this page reflects implementation quality, support responsiveness or contracted uptime. Scores reflect documented capability, published pricing and interface transparency as of October 2026 rather than prospective clinical outcomes at your site. While Isabel DDx Companion and DXplain have published vignette and resident sensitivity studies, modern LLM-based reasoning tools lack uniform, externally audited diagnostic benchmarks on live undifferentiated patients, so readers should weight their own clinical pilot heavily.

Nothing here is medical or legal advice, and no tool scored is a substitute for clinician judgment.

Common questions

Common questions about General frontier LLMs under BAA

What does General frontier LLMs under BAA score?

General frontier LLMs under BAA is scored in one of the 11 categories on this site. It scores 27/50 for clinical reasoning AI. It does not rank first in any category scored here. Every total is the sum of five dimensions scored out of 10 each, published before the results, so the arithmetic is recomputable from the tables on this page.

What is General frontier LLMs under BAA best at?

General frontier LLMs under BAA takes no full-mark dimension on this site. Its highest total is 27/50 for clinical reasoning AI, ranking 7th of 7. Teams prototyping their own reasoning workflow who want full control over prompts, retrieval and output structure.

What are the limitations of General frontier LLMs under BAA?

No clinical grounding by default and unreliable citation of primary literature, so hallucinated references are a live risk. Consumer tiers sign no BAA and cannot touch PHI. Its weakest dimension scores are 4/10 on evidence & citations for clinical reasoning AI, 5/10 on reasoning transparency for clinical reasoning AI and 6/10 on differential quality for clinical reasoning AI.

How much does General frontier LLMs under BAA cost?

Per-token pricing; BAA required for any PHI Pricing is taken from the vendor's published pricing page where one exists; where it does not, that absence is recorded rather than estimated.

What are the alternatives to General frontier LLMs under BAA?

DXplain, DynaMed, EvidenceMD and Isabel DDx Companion are scored against General frontier LLMs under BAA on at least one shared rubric. Against DXplain for clinical reasoning AI: 27–30. Against DynaMed for clinical reasoning AI: 27–34. Against EvidenceMD for clinical reasoning AI: 27–44. Against Isabel DDx Companion for clinical reasoning AI: 27–35.